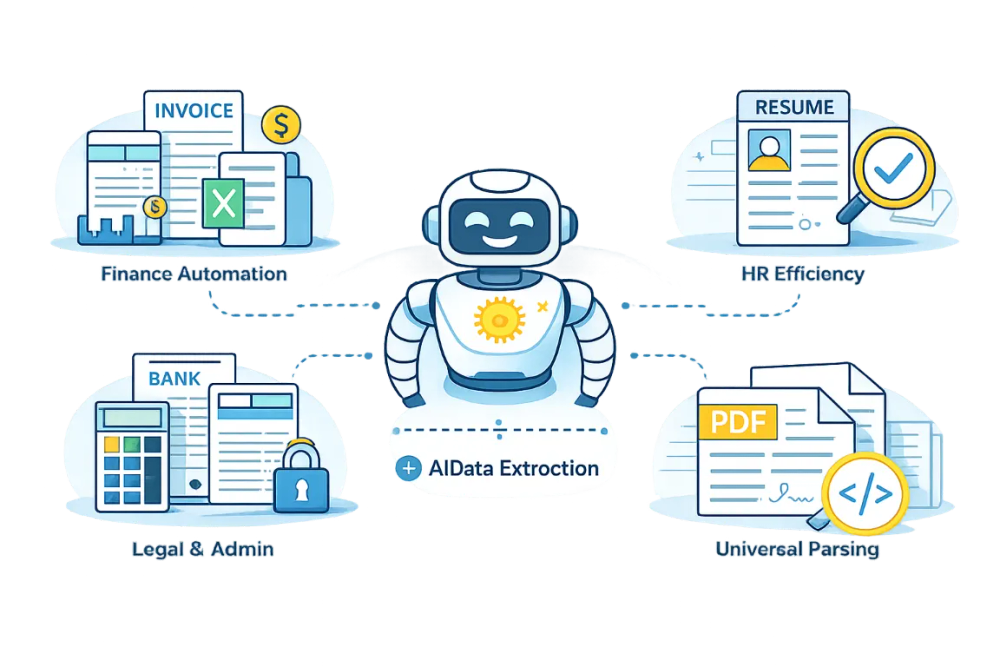
ReadyData is an advanced AI-powered PDF to Excel converter and data extraction tool designed to transform unstructured PDF data into organized, editable spreadsheets. It leverages artificial intelligence to accurately extract tables and custom fields from both digital and scanned PDF documents, including complex financial records like invoices, bank statements, receipts, and various reports. The platform streamlines data processing by eliminating the need for manual data entry, which is often prone to errors and time-consuming.
The core functionality of ReadyData revolves around its three-step process: users upload their PDF files, define the specific data points or tables they wish to extract, and then export the structured information. A key feature is the ability to handle scanned documents, where traditional copy-pasting fails due to unselectable text. ReadyData employs AI PDF extraction to intelligently read document content and structure, organizing values into spreadsheet-ready records. This capability is particularly beneficial for businesses dealing with a high volume of legacy or image-based PDFs.
Users can describe the custom fields they need, such as invoice numbers, dates, or amounts, and save these preferences as reusable templates. This templating feature significantly enhances efficiency for recurring document types, allowing for consistent and automated extraction. Before final export, ReadyData provides a review stage where users can compare the extracted tables against the original PDF, ensuring accuracy and allowing for any necessary corrections.
The output is delivered as an editable XLSX workbook, compatible with Microsoft Excel, or as JSON for integration into databases, automations, and other application workflows. This flexibility ensures that the extracted data is immediately usable for analysis, calculations, and reporting without extensive cleanup. ReadyData operates entirely in the browser, making it accessible across various operating systems like Windows, macOS, and mobile devices, without requiring any software installation. It addresses common pain points of PDF data handling, such as broken rows and columns during copy-paste, and the scalability issues of manual data entry, providing a robust solution for turning raw PDF data into actionable insights.